Skills Inference Changes Resume Writing: Do Not Make Recruiters Guess at the Wrong Evidence
Some skills taxonomies explicitly connect related capabilities, but that does not give your resume permission to be vague.[1] If a role requires Kubernetes and your bullet says only improved platform reliability, a reader may infer infrastructure experience while missing the tool, level, or ownership that matters. Skills inference adds an interpretation layer. It does not create evidence you never supplied.
The practical answer is neither keyword repetition nor blind trust in AI matching. State the few capabilities that decide role fit, then connect each one to work a reviewer can understand and you can defend.
Skills graphs recognize relationships, not your exact contribution
Skills taxonomies can describe capabilities as connected data rather than a flat list of terms. The European Commission's ESCO classification identifies relationships among occupations, skills, and qualifications.[1] Lightcast documents a taxonomy with skills organized into categories and subcategories.[2] The O*NET Content Model separately organizes occupational information through domains that include worker characteristics, worker requirements, experience requirements, occupational requirements, workforce characteristics, and occupation-specific information.[3]
Those models can plausibly connect Amazon EKS with Kubernetes or dbt with analytics engineering. They cannot determine from a tool name alone whether you evaluated an architecture, followed a runbook once, or owned production decisions for two years. Platforms also differ, and their public descriptions do not reveal one universal ranking formula.
Treat inference as a retrieval aid. Your resume still has to establish scope and credibility.
Put every priority skill in one of three zones
Start with the job-description match audit and identify the capabilities that genuinely determine fit. Then sort your evidence:
- Explicit: The skill is central to the role and to your work. Name it directly in a skills section, summary, or accomplishment, then prove it nearby.
- Inferable: Adjacent evidence makes the relationship reasonable, and the exact label is not decisive. A bullet about designing idempotent consumers can support distributed-systems experience without repeating that phrase in every line.
- Unsupported: You have exposure or a neighboring skill, but no evidence for the claimed capability. Do not ask a synonym, taxonomy, or AI rewrite to bridge that gap.
The third zone is where optimization becomes misrepresentation. Used an AWS service does not automatically prove cloud architecture. Reviewed model output does not automatically prove machine-learning evaluation. The skills evidence matrix helps expose those missing links before wording hides them.
Build a four-part evidence chain
For each explicit priority skill, map four facts:
| Element | Question | Example |
|---|---|---|
| Tool or capability | What did you actually use? | Amazon EKS |
| Context | Where and at what scale? | 12 checkout services |
| Decision | What judgment did you own? | Set pod disruption budgets and rollout thresholds |
| Outcome | What changed? | Deployment interruption alerts fell from seven per month to two |
That map produces a stronger bullet:
Configured EKS pod disruption budgets and rollout thresholds for 12 checkout services, cutting deployment interruption alerts from seven per month to two.
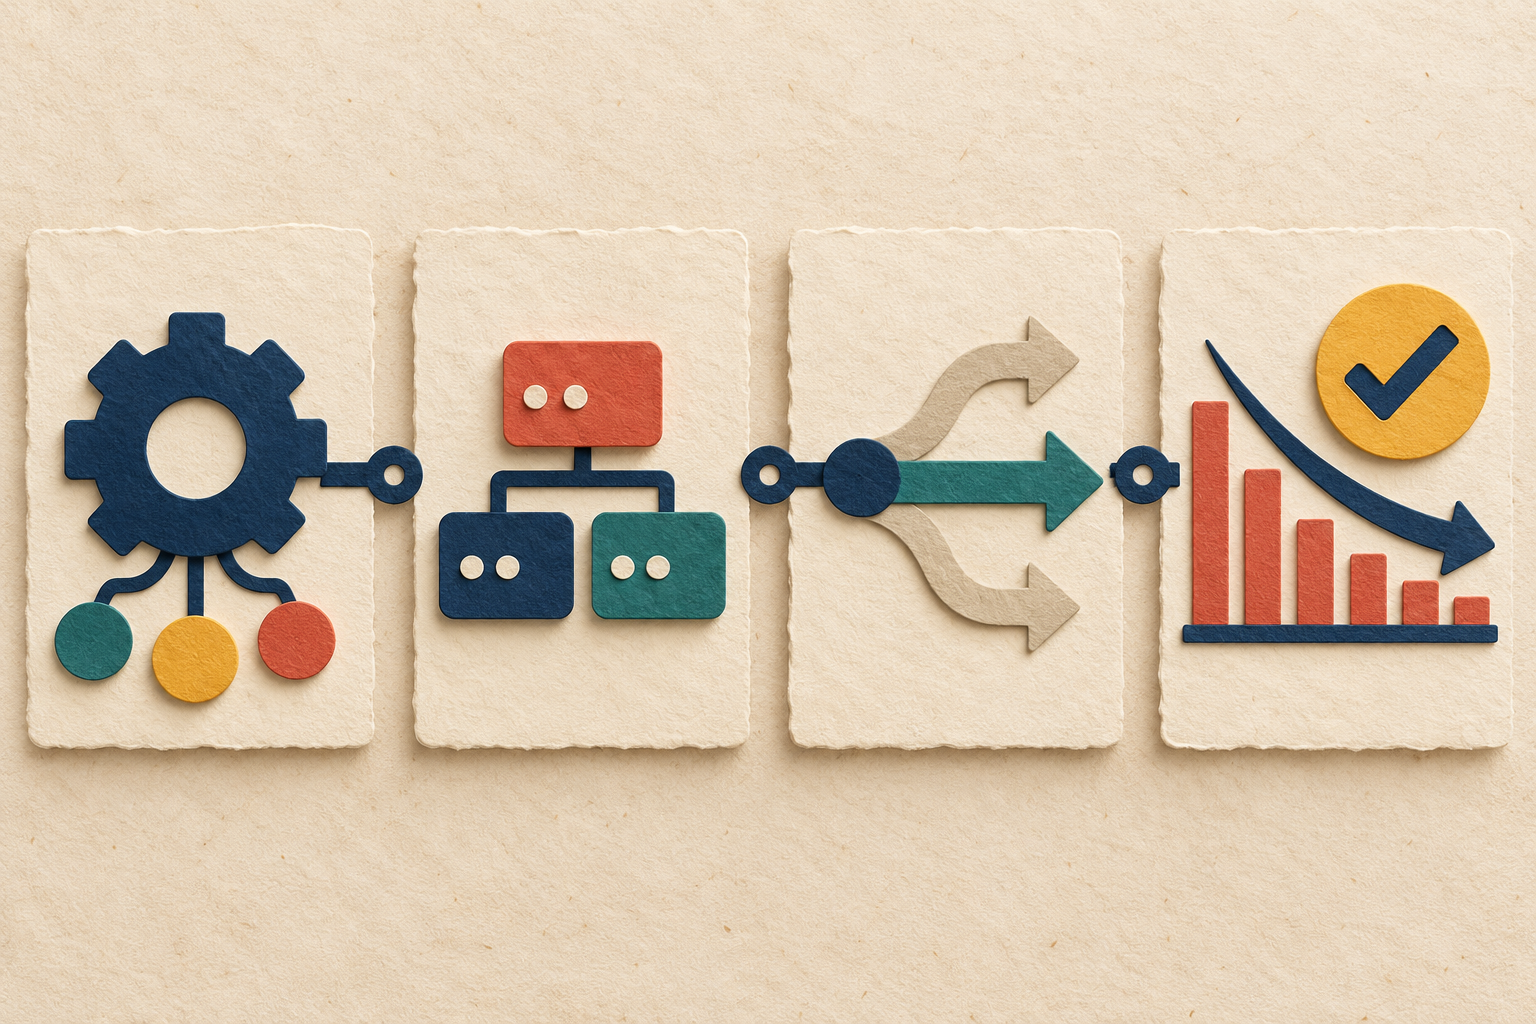
Compare it with Supported EKS platform reliability. The weaker line names a service, yet leaves level, mechanism, and proof unresolved. The stronger line gives a reader a bounded basis for connecting EKS to Kubernetes operations and gives a matching system more accurate context to work with. If Kubernetes is decisive to the role and accurately describes your experience, state it directly once rather than depending on that relationship being inferred.
Harvard's resume guidance recommends specific, active, fact-based language and tailoring information to the position.[4] That principle survives changes in screening technology because it serves both discovery and human judgment.
CoreCV can keep resumes structured and fine-tune a version against a pasted job description or job URL. Use the result to surface the strongest verified evidence, then check that no inferred relationship has upgraded exposure into expertise.
State decisive skills once, then let evidence carry them
Keyword stuffing often begins with a reasonable fear: if a term appears only once, perhaps it will be missed. The result is a summary, skills section, and several bullets repeating the same technology while saying little about how it was used.
Use hierarchy instead. Put current, role-critical technologies in a concise skills section. Prove the most important ones in experience or projects. Let adjacent terms add context only when they change the reader's understanding. The software engineer skills guide shows how to distinguish working depth from a tool inventory.
For example, a data candidate does not need SQL in every bullet:
Built dbt models and reconciliation tests for subscription revenue, tracing a duplicate-join defect that had overstated monthly renewals.
If SQL is a core requirement and truthful, list it once in the skills section. The bullet then demonstrates data modeling, validation, debugging, and business context without becoming a bag of search terms.
Run a five-minute inference audit
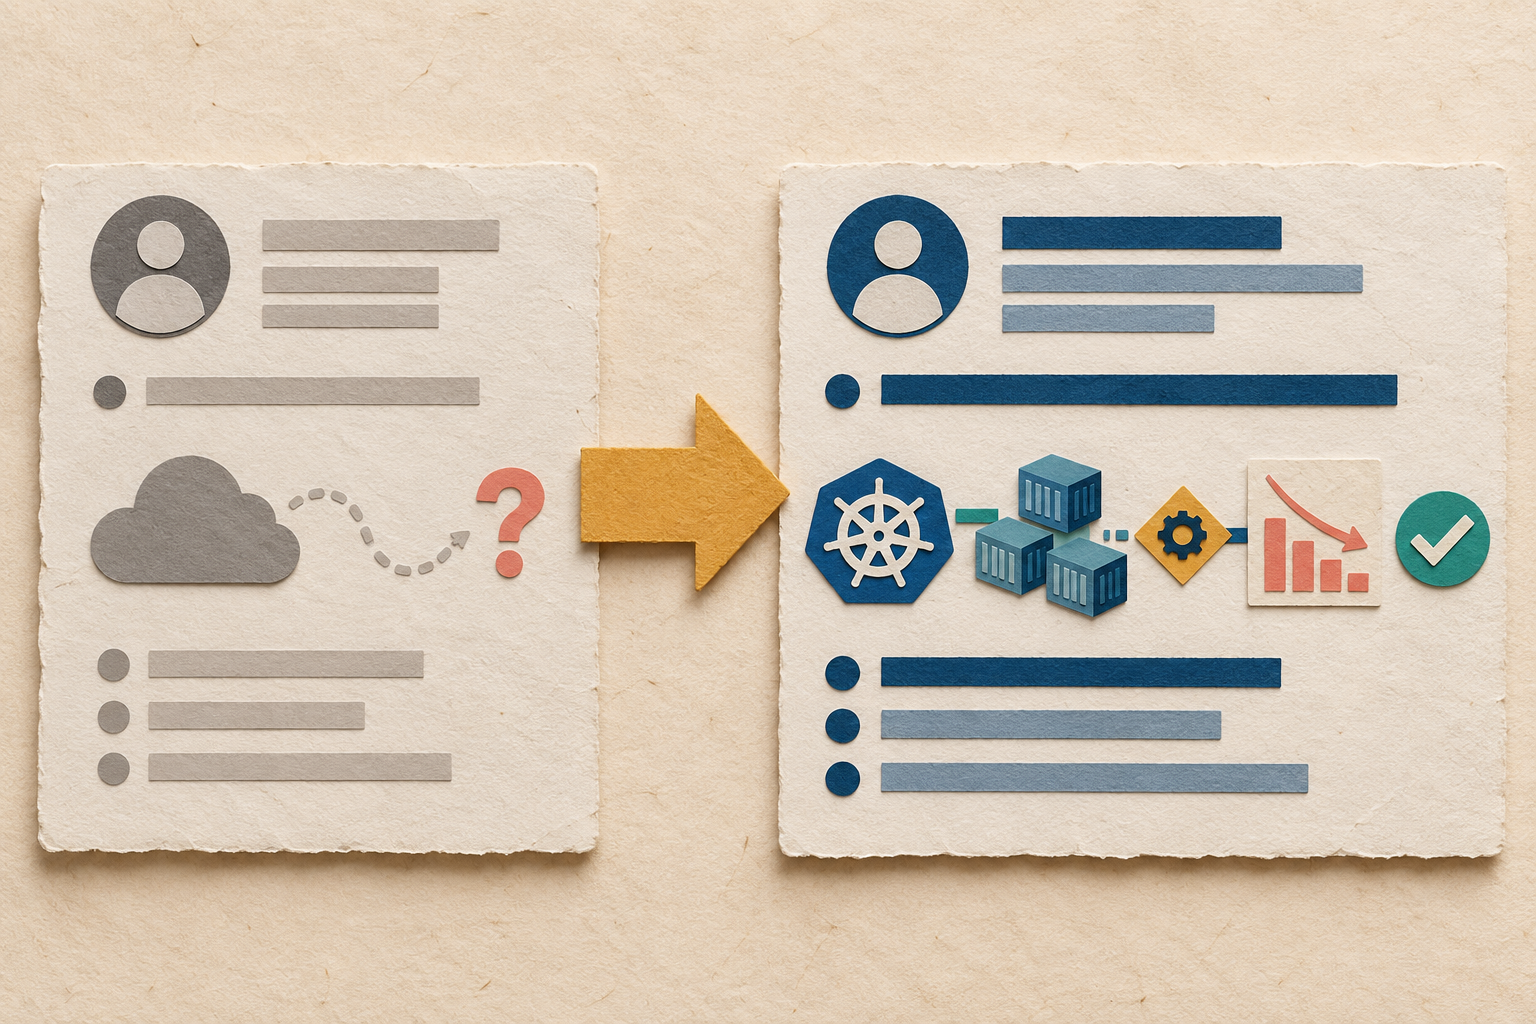
Before submitting, ask:
- Which three to five capabilities decide whether I fit this role?
- Is each one stated directly somewhere accurate and easy to find?
- Does each priority capability connect to a work or project example?
- Can a reviewer distinguish use, ownership, and decision-making depth?
- Did any rewrite convert adjacency into a claim I cannot defend?
If a hiring disclosure mentions AI-assisted screening, read the actual disclosure instead of assuming how the system works. The AI screening guide explains why ranking, matching, and decision-making should not be treated as interchangeable.
Your job is not to predict a proprietary model. Make the intended inference easy: name the decisive skill, attach it to bounded evidence, and remove claims that depend on generous interpretation. Better matching then becomes a useful path to the same conclusion a careful human should reach.
Follow the CoreCV Blog via RSS for practical weekly guidance on making technical value legible in an AI-shifting hiring market.
Sources
1. European Commission, What is ESCO?: https://esco.ec.europa.eu/en/about-esco/what-esco
2. Lightcast, Skills Taxonomy: https://docs.lightcast.dev/lightcast-api/docs/skills-taxonomy
3. O*NET Resource Center, O*NET Content Model: https://www.onetcenter.org/content.html
4. Harvard Mignone Center for Career Success, Create a Strong Resume: https://careerservices.fas.harvard.edu/resources/create-a-strong-resume/