The Next AI Career Signal Is Whether Your Work Made the Team Better
For many technical candidates, using AI well by yourself is no longer a distinctive signal. The more revealing career question is what happened around you: Did a useful experiment become a repeatable workflow with a standard, a safe environment, or a better way to review output? Individual fluency matters, but work that raises the capability of other people creates a stronger and more durable signal.
Two recent sources make that shift unusually visible. Anthropic's Claude Frontier Academy says its program is for hands-on engineers with strong fundamentals, a record of building with LLMs, experience helping others adopt AI, and a named project to lead. Participants move from a simulated deployment through security review, handover, and a graded practical, then lead a real 12-week deployment in their own organization.[1]
That is one vendor's selective program, not a universal hiring standard. Still, its design is instructive. The assessment does not end when a candidate produces a clever output. It follows the work into an organization, where adoption, security, operational fit, and handover become part of competence.
DeepLearning.AI made a parallel argument to engineering leaders this week. Its People, Projects, Platforms, and Processes framework says team proficiency requires individual hands-on practice, organizational backing for promising projects, shared infrastructure and context, and redesigned ways of working with safeguards.[2] Again, this is directional advice, not labor-market proof. The overlap between the two sources is the useful part: AI capability becomes organizational only when people other than the original builder can use it responsibly.
For candidates, that creates a practical opening. You do not need a frontier title, a management role, or a company-wide transformation story. You need credible evidence that your AI work became repeatable across a boundary between people. This article shows how to build and present that evidence without inflating a pilot into a revolution.
Solo fluency has a career-evidence ceiling
A tool list can establish exposure. A polished demo can establish that you made something work once. Neither tells an employer whether the practice improved a team's real operating capacity.
Consider four increasingly strong claims:
- "I use an AI coding assistant."
- "I used an assistant to reduce the time I spent writing tests."
- "I created a reviewed test-generation workflow with acceptance checks and shared it with the team."
- "Five engineers adopted the workflow, review caught two failure patterns, and we revised the checklist before expanding it."
Each step exposes more of the system around the tool. The fourth claim shows a useful task, a reusable method, other people's behavior, a quality boundary, and a revision based on evidence. It is more credible because more parts of it can be challenged.
This does not mean every valuable project must spread across a company. A difficult individual contribution can be excellent evidence. The point is narrower: when you claim collaboration, enablement, adoption, or organizational impact, the proof must extend beyond your own output. "Evangelized AI" and "drove transformation" are weak when nobody can see what changed.
The best team-enablement stories usually leave artifacts behind. They include a runbook, evaluation set, reusable skill, template, policy, office-hours record, before-and-after workflow, review rubric, adoption log, or decision memo. Those artifacts let a reviewer distinguish a motivational presentation from capability that another person could actually use.
Use TEAM to make the signal inspectable
Build the story around four elements: Task, Enablement, Adoption, and Measurement. TEAM is not a maturity model and it does not require a formal rollout. It is a way to make your contribution specific enough to evaluate. Safety and handoff sit across the framework because each element needs a boundary and an owner: the task defines what remains human-owned, enablement makes safe use repeatable, adoption tests whether those boundaries hold in practice, and measurement determines whether the capability should continue or change hands.
Task: start with a recurring constraint
Weak enablement begins with a tool and searches for people to train. Strong enablement begins with work that repeatedly costs time, loses quality, or creates avoidable risk.
Name the actual task, the people doing it, the frequency, and the consequence of getting it wrong. "Helped the support team use AI" says almost nothing. "Helped six support engineers draft incident summaries while preserving source links and escalation ownership" gives the work a boundary.
Before building anything, observe the existing path. Where does judgment enter? Which inputs are available? What is already standardized? What data cannot go into an external tool? What would a reviewer need to accept the output? Sometimes the right contribution is a retrieval improvement, a deterministic check, or clearer documentation rather than a new prompt.
DeepLearning.AI's framework emphasizes that AI projects need both bottom-up experimentation and organizational backing to scale.[2] A candidate does not need to claim executive sponsorship. Do record the local owner who agreed that the problem was worth testing and the condition under which the pilot would stop.
Enablement: reduce the cost of doing the work well
Enablement is the shared layer that helps another person achieve a reliable result. It might be technical:
- a versioned workflow with defined inputs and outputs
- a representative evaluation set and grading rubric
- a safe sandbox with approved data
- a reusable agent skill, integration, or CI check
- observability and an escalation route
It can also be operational:
- a decision guide for when to use the workflow
- examples of acceptable and unacceptable output
- a short practice exercise with feedback
- a review checklist tied to real failure modes
- a named maintainer and update process
The distinction matters because a lunch-and-learn is an event, while enablement changes the cost of correct action afterward. Slides may help, but the strongest artifact is usually what a teammate uses when you are absent.
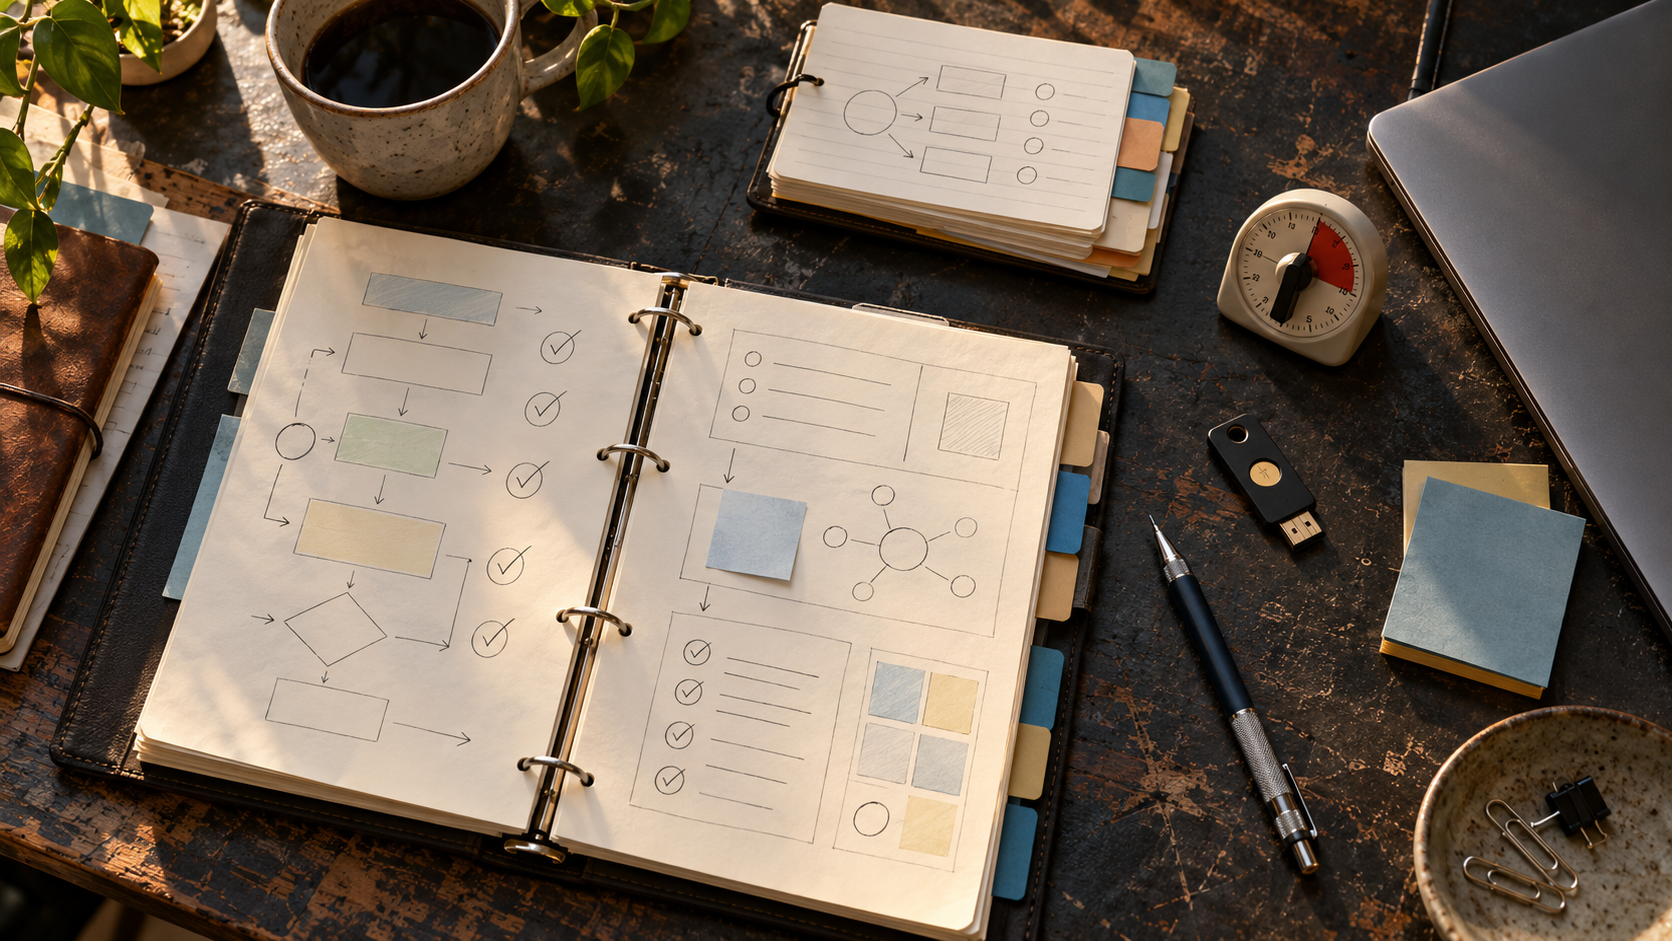
Reusable artifacts turn a private technique into something a teammate can inspect, practice, and run without the original builder present.
This is where the new source material differs from a simple tool-training story. Anthropic's program moves participants through use-case selection, security review, deployment, and handover before assessing them again after real organizational work.[1] The exact curriculum belongs to Anthropic. The transferable principle is that fluency must survive contact with constraints and other operators.
If your workflow is reusable, publish only what you are authorized to share. Replace employer data with synthetic examples, remove proprietary prompts, and describe the contract rather than exposing private context. The portable AI workflow framework offers a deeper method for packaging inputs, checks, permissions, and failure handling.
Adoption: show voluntary use and useful friction
Downloads, attendees, licenses, and account activations are activity counts. They do not establish that a workflow improved anyone's work. Better adoption evidence answers three questions:
- Who tried the workflow on a real or representative task?
- What made them continue, modify, or stop using it?
- What changed because of their feedback?
Evidence can be modest. Two teammates completing a structured pilot and identifying a missing review step is more informative than 80 people attending a demonstration. A reviewer note that changed the template is evidence. A team choosing not to use the workflow for regulated data is also evidence of sound boundaries.
Adoption is not obedience. If you had authority over the participants, say how feedback was collected and whether people could reject the tool. If usage was mandated, do not present the number of required users or sessions as evidence that people found the workflow valuable. If the pilot failed, preserve the reason. A candidate who can explain why a workflow was abandoned may show better judgment than one who forces a weak practice into production.
Useful adoption evidence includes the friction people find and the revisions their real use produces.
A useful handoff test is simple: can a teammate identify when the workflow applies, run it with approved inputs, evaluate the result, recover from a known failure, and find the owner when conditions change? If not, the capability still depends on you. Our guide to AI workflows that survive a handoff expands that test into portfolio evidence.
Measurement: compare accepted outcomes, not generated volume
Team enablement produces tempting vanity metrics. Prompts run, tokens consumed, suggestions accepted, and hours "saved" can become large numbers with weak foundations. Measure the work at the point where someone accepts an outcome.
Choose a small set of measures that match the task:
- completion time for an accepted artifact
- reviewer corrections by failure type
- percentage of cases requiring escalation
- invalid or unsupported output rate
- repeat use after the initial pilot
- time needed for a new person to complete the workflow
- incidents, near misses, or policy exceptions
Define the baseline and collection method. If participants estimate time saved, label it as self-reported. If the sample is small, provide the count. If quality was judged by one domain expert, say so. Do not turn a four-person pilot into an annualized company saving.
NIST's AI Risk Management Framework treats measurement and management as continuing functions across an AI system's lifecycle, with responsibilities distributed across roles rather than confined to a model builder.[3] A portfolio project does not need enterprise governance ceremony. It does benefit from the same discipline: define the context, identify risk, measure the result, assign review, and revise when evidence changes.
If you are tailoring this team-impact evidence to a role, CoreCV's role-targeted resume workflow can help you emphasize the most relevant verified details against a pasted job description or job URL. Keep the underlying facts fixed while changing which part of the evidence chain leads.
Worked example: from a private shortcut to a shared incident-summary workflow
Imagine a platform engineer who uses an LLM to draft summaries after lower-severity incidents. The initial shortcut saves the engineer some writing time, but it also creates risks. A summary can omit the timeline, invent causality, expose sensitive logs, or imply that a hypothesis was confirmed. No one else knows which inputs are safe or how the draft was checked.
The following example is illustrative. Its numbers are not CoreCV customer results or claims from the cited sources.
Step 1: define the task and boundary
The engineer interviews the incident commander and two service owners. They agree that the workflow may draft the factual timeline and assemble links from approved incident artifacts. It may not determine root cause, assign blame, publish externally, or use raw customer records. A human incident owner remains responsible for the final summary.
The baseline sample contains 18 completed lower-severity incidents. The team records how long first drafts took, which sections reviewers corrected, and which incidents should never enter the pilot. Six representative incidents become a development set. Six later cases are retained for a small holdout check. The remaining cases help define failure examples.
Step 2: build the enablement layer
The engineer creates a template with required fields for confirmed facts, open questions, timestamps, source links, and owner. The model must attach a source marker to every timeline claim. A deterministic check rejects missing links and unsupported services. A short runbook defines approved inputs, restricted data, escalation conditions, and the person who can change the template.
The workflow also includes three deliberately difficult practice cases: conflicting timestamps, an unconfirmed root-cause hypothesis, and a log excerpt containing customer information. Teammates must identify why each case needs correction or exclusion before using the workflow on a fresh incident.
This package is more valuable than the prompt. The template defines the output contract. The practice cases teach judgment. The checks catch cheap failures. The ownership record explains what happens when the system no longer fits.
Step 3: run an adoption pilot
Three engineers use the workflow on six new lower-severity incidents. After each case, the incident owner records draft time, corrections, escalation, and whether the draft was accepted as a useful starting point. The pilot reveals two problems.
First, the source-link check confirms that a link exists but not that it supports the sentence. The team adds a review rubric that asks the owner to inspect the cited passage. Second, engineers treat "open questions" as optional when the draft sounds confident. The template changes so unresolved hypotheses must appear before the narrative summary.
One engineer opts out for an incident involving restricted customer data. That is not an adoption failure. It is evidence that the boundary was understood.
Step 4: measure and hand off
Across the six-case pilot, five drafts are accepted as useful starting points and one is discarded after source conflicts. Median drafting time falls in the pilot sample, but review time rises slightly because owners inspect source support more carefully. The engineer reports both. The result is not "AI made incident response 40% faster." It is a bounded finding: for this small class of incidents, the workflow accelerated drafting while adding a more explicit verification step.
The engineer then asks a colleague who did not build the system to run one practice case from the documentation alone. The colleague misses the escalation rule for conflicting timestamps, so the runbook is revised. Ownership transfers to the incident-process working group, with a monthly sample review and a trigger to suspend the workflow after any unsupported causal claim reaches publication review.
That project now supports a defensible career story. The engineer did not merely use AI. They found a recurring task, negotiated a boundary, built reusable support, observed real use, learned from failure, measured accepted outcomes, and transferred ownership.
Publish the capability, not another framework
Turn the worked example into a short portfolio narrative rather than repeating TEAM as six more headings. Open with the operating problem, users, baseline, and consequence of error. Show one shared artifact in enough detail to invite a challenge, then explain who tried it, which guardrail changed behavior, and what their feedback forced you to revise. Close with the current owner, limitation, and condition that would suspend or retire the workflow.
That narrative complements a technical repository. Code shows implementation; the capability record explains why other people could rely on it. A public project can include a small enablement folder with the sanitized task contract, representative cases, review rubric, changelog, and handoff notes. If the work stopped at a pilot, label it as a pilot.
Rewrite resume bullets around multiplication
Team-enablement bullets often fail in one of two directions. They are either vague leadership claims or overloaded mini case studies. Lead with the changed team capability, then select one adoption or quality measure that you can defend.
Weak:
Trained developers on ChatGPT and drove AI adoption across engineering.
Stronger:
Piloted an AI-assisted incident-summary workflow with three platform engineers, publishing approved-input and source-review criteria and revising the runbook after six representative incident exercises.
Weak:
Created AI best practices that increased productivity.
Stronger:
Standardized AI-assisted test generation for two services with a shared acceptance rubric and CI checks; onboarded five engineers and tracked review corrections during a four-week pilot.
Weak:
Led organization-wide AI transformation.
Stronger, if accurate:
Coordinated a cross-functional pilot for support-response drafting, defining restricted-data boundaries, reviewer ownership, and a suspension rule before the workflow expanded to 12 agents.
The stronger versions do not need a dramatic percentage. They show scope, artifact, use, and control. If you have a measured result, add it only when the denominator and method survive follow-up. The auditable resume bullet framework can help separate observation, calculation, attribution, and business meaning.
Tailor the lead based on the role. A developer-experience position may care about onboarding time and reusable tooling. A platform role may care about approved context, sandboxing, CI, and observability. A product role may care about selecting the task and interpreting adoption. A security role may care about data boundaries, threat cases, and escalation. The project remains the same; the most relevant verified evidence moves forward.
Tell the interview story as a change in the team's system
Do not spend the whole interview narrating the prompt or architecture. Start with the team's recurring friction and the boundary agreed before the pilot. Describe the shared capability you built, who tried it, and the correction their use produced. End with ownership: who maintains the practice now, and what evidence would stop it.
Expect attribution questions. Be ready to separate what you built from who selected the use case, approved the data boundary, taught the sessions, measured the result, and owned the final decision. Give collaborators credit. A story about team enablement loses credibility when every sentence makes you the sole actor.
Also prepare to explain a dissenting view. Perhaps a security partner rejected one data source, an experienced engineer found the process slower, or a team preferred a deterministic tool. Show how you investigated the objection. Enablement is not the art of persuading everyone to use AI. It is the work of helping a group make better, safer decisions about where AI earns a place.
Decode job descriptions for this signal
Employers rarely write "make individual AI fluency repeatable across a team." Look for clusters of verbs and nouns instead.
| Posting language | Likely underlying need | Evidence to foreground |
|---|---|---|
| Enable, mentor, champion, train | Raise hands-on capability | Practice exercise, office hours, feedback, independent use |
| Standardize, scale, operationalize | Make a workflow repeatable | Contract, runbook, reusable component, ownership |
| Govern, secure, review | Preserve boundaries as use spreads | Approved inputs, access, escalation, audit trail |
| Drive adoption, influence, partner | Change behavior across roles | Pilot design, objections, opt-outs, revision |
| Platform, developer experience, tooling | Lower the cost of correct use | Shared context, sandbox, CI, observability, support load |
| Measure, optimize, improve | Learn from accepted outcomes | Baseline, sample, correction rate, repeat use |
One verb is not enough to infer the job. Read the responsibilities around it and ask how the team currently works. Our guide to decoding AI language in job descriptions offers a task, consequence, verification, and boundary framework for that conversation.
Useful interview questions include:
- Which AI-assisted practices have moved beyond individual experiments?
- What prevents a successful pilot from becoming a supported team workflow?
- Who owns approved tools, context, evaluation, and incident response?
- How do you distinguish adoption from mandatory usage or license activation?
- What would this person be expected to leave the team able to do after six months?
The answers reveal whether "AI enablement" means building a real internal platform, coaching peers, selling a tool, absorbing unsupported experiments, or simply using an assistant personally. Do not import the Anthropic program's expectations into every role. Use its specificity as a reminder to investigate what the employer means.
Build the signal without formal authority
You can create credible evidence in a small team, open-source project, volunteer group, or study cohort. Keep the scope narrow and obtain consent before involving other people or their data.
In the first week, interview two or three potential users and observe one repeated task with a clear output. Record what remains human-owned, which inputs are off limits, one quality measure, and one reason to stop. During the second week, build the smallest useful shared layer: perhaps a template, evaluation set, checklist, or sandbox. Include good, bad, and boundary cases, then ask a domain-aware reviewer to challenge it.
Use the third week for a consent-based pilot with two or three people working on synthetic, public, or authorized material. Watch where the documentation fails and collect corrections, decisions, opt-outs, and negative feedback without retaining private transcripts. In week four, revise the workflow and ask someone new to use the documentation without live coaching. The final package is compact: a sanitized case study, one resume bullet, and an interview explanation that names the scope, result, limitation, and owner.
If nobody adopts the result, you still have useful evidence if you can explain what blocked adoption and what you changed. Do not relabel an individual demo as enablement. A small honest pilot is stronger than a fictional transformation.
The durable signal is what remains after you leave the room
AI fluency begins with hands-on use. It becomes team capability when other people can apply it to a worthwhile task with shared standards, appropriate context, visible boundaries, and evidence that drives revision.
The fresh sources do not prove that every employer will screen for this pattern. One vendor program treats security review, practical assessment, real deployment, and handover as parts of competent AI work, while an engineering-leadership essay argues for organizational support across people, projects, platforms, and processes. Together, they offer a useful prompt for candidates rather than a universal standard.
Ask of your next AI project: What will the team be able to do responsibly after I am no longer in the room? Preserve the shared artifact, adoption trail, guardrail, measured correction, and handoff. That record turns a private productivity claim into career evidence another person can inspect.
For one practical research breakdown each week, follow the AI Career Signals archive. The series translates changes in AI work into decisions you can use across your resume, portfolio, interviews, and job search.
Disclosure: This article is authored by the CoreCV team. While we mention CoreCV.ai, the strategies and advice presented here are intended to be useful whether or not you use our product.
Sources
1. Anthropic, "Claude Frontier Academy", October 2, 2026, updated October 13, 2026.
2. Andrew Ng, DeepLearning.AI, "How Engineering Leaders Can Help Their Teams Become AI-Native", October 23, 2026.
3. National Institute of Standards and Technology, "Artificial Intelligence Risk Management Framework (AI RMF 1.0)", January 2023.